AI Coding Works Better When the Agent Has a Contract
AI Coding Works Better When the Agent Has a Contract
The biggest improvement in my AI-assisted development workflow didn’t come from switching to a better model. It came from giving the model less room to misunderstand the system.
I use coding agents regularly on a real multi-tenant SaaS codebase: backend, frontend, database, background jobs, APIs, authentication, document processing, AI workflows, deployment, tests. There are enough moving parts that a confident mistake in the wrong place gets expensive very quickly.
Over time my workflow changed. At first I mostly gave agents tasks. Now I spend much more effort designing the environment in which the agent performs the task: persistent documentation, explicit constraints, plans before implementation, small slices, preflight audits, and postflight verification.
None of this is a formal methodology, and I’m not claiming it’s the correct way to work with coding agents. It’s the workflow I gradually converged on after watching agents succeed, drift, over-engineer, misunderstand requirements, fix the wrong problem beautifully, and occasionally produce something much better than I expected.
First: this is not quite the same thing as vibe coding
The terminology here is still surprisingly fuzzy, so it’s worth pinning down.
Andrej Karpathy has used agentic engineering to separate a more serious engineering discipline from vibe coding: the goal is to get more leverage from increasingly capable agents without giving up the quality bar expected from professional software.
That matched something I had already started noticing in my own work. I was reminded of it recently during a technical interview (I wrote a bit more about that interview, and about what live coding doesn’t measure, in AI Coding Agents Are Great. Until Someone Asks You to Code Without One.). We were discussing a product I had built with substantial AI assistance, and the interviewers mentioned that they also “vibe code” some things from time to time. It made me realize we may be using the same phrase for several rather different ways of working.
I do sometimes vibe code, and it’s great. If I need a throwaway script, a small tool, a prototype, a UI experiment, or anything where being slightly wrong is cheap, I’m perfectly happy to explain what I want, let the model produce something, run it, poke at it, fix whatever smells strange, and move on. There’s nothing wrong with that.
But I don’t want to change authorization logic in a multi-tenant system that way, or a payment flow, or an API contract consumed by another application, or a database migration that touches production data. The tools can be identical while the operating discipline is completely different.
The way I think about it, roughly:
Vibe coding optimizes for getting from intent to working output with very little ceremony.
Agentic engineering uses the same class of tools, but keeps professional engineering constraints around them: specification, decomposition, review, testing, architecture, security, and accountability.
What separates them isn’t who typed the code. It’s how much engineering structure exists around the generation, and the more important the software becomes, the more I care about that structure.
The dangerous prompt is often the reasonable-looking one
Consider a perfectly normal request:
Add assessment awareness to the chat assistant.
A capable coding agent can work with that. It can inspect the repository, find the chat handler, discover the assessment models, wire things together, write a few tests, and return an impressive-looking diff. It may even work.
The trouble is everything hidden behind that sentence. Which assessment? The latest completed one? Can deleted assessments appear? What is the stable identifier for a control? What happens if the user asks a generic question and no assessment context should be injected? Does the chat layer own the matching logic, and can Infrastructure access the database directly? What does Unknown mean? Can an uploaded policy be treated as proof that a process actually operated? Should the feature work across several compliance frameworks? What should happen if semantic matching fails?
The agent doesn’t necessarily know which of these are architectural constraints, business rules, historical accidents, or things I simply haven’t thought about yet. If I leave the space blank, it has to fill it, and models are very good at filling blank spaces with plausible things. That’s both their superpower and their problem.
The agent often does not fail because it cannot write the code. It fails because it can write a lot of perfectly plausible code based on the wrong interpretation.
So my workflow increasingly tries to close those interpretation gaps before implementation starts.
Persistent context beats explaining the system again and again
One of the most useful changes I made was treating repository documentation as part of the agent’s working environment.
I already needed documentation for myself: architecture notes, API contracts, feature specifications, module descriptions, deployment notes, data shapes, important invariants. Once coding agents became a regular part of the workflow, these documents picked up a second purpose and became persistent context.
Instead of repeatedly explaining:
This is a modular monolith. Application owns orchestration. Infrastructure implements abstractions. Tenant scope must always come from the active tenant context. Don’t put AI calls in endpoints.
I can make that knowledge available in the repository.
The documentation doesn’t need to describe every class. Trying to document everything would probably create a second stale codebase made of Markdown. I care more about documenting the things the agent must not invent: architectural boundaries, domain terminology, important data relationships, API contracts, tenant and authorization rules, expected feature behavior, deployment assumptions, and unusual historical constraints.
This changed how I see technical documentation.
Documentation stopped being something I wrote only for future humans. It became part of the execution environment for agents.
There’s direct tooling support for this idea now, though the conventions differ. GitHub Copilot supports repository instructions such as .github/copilot-instructions.md and scoped instruction files. Cursor has project rules and supports files such as AGENTS.md. Claude Code commonly uses CLAUDE.md for persistent project guidance, along with related mechanisms such as skills and hooks. The exact filenames and mechanisms will keep evolving, so I wouldn’t build a philosophy around any single one of them. The durable idea is simpler:
Do not make every coding session start from organizational amnesia.
For someone just getting started with coding agents, one of the first useful questions is:
What persistent project-instruction mechanism does my tool support?
If you keep telling the agent the same stable rules every session, those rules probably belong somewhere more permanent than today’s chat.
I started treating prompts as temporary contracts
Persistent documentation describes the system, but a task needs something more specific. For larger changes I increasingly create what I think of as an AI contract. That sounds grander than it is: it’s a short specification of what the agent is being asked to accomplish and what boundaries it must respect.
For example:
Goal

Make chat responses aware of relevant assessment findings.

Scope

- Resolve assessment context for specific user questions.
- Add that context to the existing chat pipeline.
- Keep existing document RAG behavior.

Constraints

- Preserve tenant scoping.
- Do not move business logic into API endpoints.
- Do not change the assessment persistence model.
- Existing explicit control-code lookup must continue to work.
- Unknown is a valid assessment state.
- Document existence must not automatically be treated as evidence of execution.

Out of scope

- Database schema changes.
- UI redesign.
- New compliance frameworks.

Done when

- relevant natural-language questions can resolve assessment context;
- generic questions do not force an assessment match;
- current behavior remains backward compatible;
- targeted tests cover success and fallback paths;
- existing relevant tests remain green.
It’s not particularly sophisticated, and that’s part of the point. It moves important assumptions out of my head and into a form that both the agent and I can inspect, and it gives us something to compare the final implementation against.
I stopped thinking of these prompts as clever instructions and started treating them as temporary contracts. An instruction says what I want now. A contract lets me ask later:
Did we actually build what we agreed to build?
Plan first, implementation second
Another habit I’ve adopted is asking for an implementation plan before allowing substantial changes. Not a five-page architectural essay, just a practical plan: which components are involved, which files are likely to change, where the new logic should live, which existing abstractions can be reused, whether the public API or persistence changes, what tests should be added, and which assumptions are risky.
This gives me a useful checkpoint. If the agent thinks the feature requires changing seven API contracts and introducing three new abstractions, while I expected a small Application-layer change, I want to have that argument before it starts editing files. A bad plan costs a few minutes, and a bad implementation spread across twelve files costs a lot more.
Fixing a wrong plan is cheap. Fixing a wrong interpretation after it has become architecture is not.
Sometimes reviewing the plan shows that my own task description was poor, because the agent asks a question I failed to ask myself. In that case the planning step has done real engineering work before a line of code exists.
Reduce the decision surface with bounded slices
Large requests invite large interpretation spaces, so I increasingly split changes into bounded slices. Instead of:
Implement assessment-aware chat.
I might end up with something closer to:
- expose candidate controls from the latest assessment;
- define a semantic selector abstraction;
- implement selection without database access;
- validate selected identifiers against known candidates;
- extend assessment context resolution;
- inject resolved context into the existing chat pipeline;
- add targeted tests;
- run integration regression tests.
This isn’t classic vertical slicing in the strict architectural sense every time. The point is to reduce how many independent decisions the agent has to make at once. A good slice is understandable in isolation, bounded in responsibility, independently testable, small enough for a meaningful diff review, and reversible without dismantling half the feature.
The principle I keep coming back to:
The larger the task, the more aggressively I try to reduce the agent’s decision surface.
It also helps with context limits, since an agent working on one coherent slice needs fewer assumptions loaded at once than an agent trying to redesign an entire subsystem.
Before code, run a preflight
One practice I find disproportionately useful is a preflight audit. Before implementation, I explicitly ask the agent to look sideways.
For a reasonably contained change, that may be nothing more than a short checklist:
Before implementation, audit the proposed change for:

- architecture and layering impact
- database/schema/migration impact
- public API contract impact
- authentication and authorization
- tenant isolation
- background jobs
- configuration/environment variables
- backwards compatibility
- test coverage
- deployment implications

Do not modify code yet.

Report:
1. affected areas
2. risks
3. assumptions
4. anything requiring a decision before implementation
For larger or more cross-cutting work I sometimes make the audit much more specific. This is especially useful after several implementation slices have already landed and I want to verify that the system is still internally consistent before continuing.
One recent audit prompt, shortened considerably, looked like this:
You are performing a READ-ONLY consistency and authorization audit.

DO NOT modify code.
DO NOT redesign architecture.
Do not speculate.

Use the current implementation and these repository documents as
the source of truth.

Goal:
Verify that recent assessment changes remain consistent with:
1. assessment freshness semantics;
2. immutable assessment history;
3. Consultant authorization.

Check specifically:
- whether context changes can affect future assessments while old
  assessments still report themselves as Fresh;
- whether reruns preserve historical context;
- whether Consultant access was accidentally narrowed;
- whether frontend and backend authorization disagree.

For every finding:
- cite the exact file/class/method;
- classify it as PASS, PARTIAL, or FAIL;
- distinguish semantic gaps from authorization bugs.

Do not propose implementation changes yet.

Finish by answering:
1. What is inconsistent?
2. What is actually blocked?
3. What must be fixed before the next implementation slice?
The real prompt was considerably longer. It named the exact profile fields and variables involved, pointed to the relevant planning documents, required authorization matrices, and included a concrete post-handoff scenario that crossed backend permissions, frontend guards, immutable assessment history, and freshness semantics. That level of detail wasn’t verbosity for its own sake: every added constraint was a decision I didn’t want the agent to make silently. I’m not asking it to “review the code.” I’m defining what correctness means before the review starts.
I also increasingly prefer scenario-based audits over purely structural ones. Instead of asking:
Is Consultant authorization correct?
I can describe the workflow that must remain possible:
Owner hands off routine compliance work to Consultant.

1. Consultant opens an existing completed assessment.
2. Consultant sees interpreted evidence and source freshness.
3. Consultant updates current client context.
4. Consultant reruns the assessment.
5. A new immutable assessment is created.
6. The previous assessment remains historically intact.
7. Consultant opens the diff between runs.
8. Owner intervention is not required for routine assessment work.

Classify every step as:
- ALREADY SUPPORTED
- BLOCKED BY AUTHORIZATION
- UI BLOCKED
- SEMANTIC CONSISTENCY GAP
- UNKNOWN
That forces several layers of the system to meet in one place. A backend endpoint can look correct in isolation, a frontend guard can look correct in isolation, and the persistence model can preserve history perfectly, yet the actual user workflow is still broken once they’re combined. A concrete scenario gives the agent less room to declare success after inspecting only one layer.
Not every checkbox matters for every task. Changing button copy probably doesn’t deserve a database migration audit. The point isn’t ritual compliance, it’s forcing the agent to inspect possible consequences before it commits to a solution, or, after a sequence of changes, before I let it keep building on assumptions that may already have drifted.
This catches an interesting class of failures. Agents are often very good at the direct path (need X, find code for X, modify X), while real systems frequently break because of something adjacent to X: a serialization contract, a worker, a configuration value, a tenant filter, an old API consumer, a deployment environment variable, a migration nobody remembered, or two individually correct authorization rules that produce the wrong end-to-end workflow when combined. The preflight isn’t about perfect prediction. It’s about nudging the agent to look sideways before moving forward.
By the time coding starts, coding should be boring
There’s a funny consequence to all of this. Once the agent has repository context, a task contract, an agreed plan, bounded scope, and a preflight assessment, the actual implementation often becomes the least interesting part of the process. That’s good. By the time the agent is allowed to write code, most of the expensive arguments should already have happened.
At that stage I’m happy for it to be fast: generate the boilerplate, add the interface, wire the dependency, write the DTO, update the handler, add the tests, run them. Implementation is cheap once the ambiguity has been squeezed out, and that’s where the coding agent is exceptionally valuable.
It’s also why “how many lines of code did AI generate?” isn’t a metric I find interesting. If AI writes 2,000 lines solving the wrong problem, its typing speed hasn’t helped me much.
“All tests pass” is not the end
Coding agents love telling you they’re done, and they usually have supporting evidence: the build succeeded, the tests passed, linting passed, no compiler errors. That’s useful, but it isn’t sufficient.
My postflight increasingly looks roughly like:
Build
  ↓
Targeted tests
  ↓
Relevant broader tests
  ↓
Inspect diff
  ↓
Compare implementation with original contract
  ↓
Check architectural boundaries
  ↓
Look for unrelated changes
One prompt I find useful conceptually is:
Compare the final implementation with the original task contract and plan.

Identify:

- deviations from the agreed scope
- assumptions introduced during implementation
- unrelated changes
- missing test cases
- backwards-compatibility risks
- remaining architectural or operational risks

Do not change the implementation yet.
That last sentence matters. Otherwise an agent asked to review its own work may immediately start “improving” it and create a second moving target.
There’s a broader lesson in here:
“All tests pass” is useful information. It is not proof that the agent understood the requirement.
A unit test can prove that an implementation behaves as its author expected. If the implementation and the tests share the same wrong assumption, the suite can be beautifully green.
Most of my guardrails came from something going wrong
I didn’t sit down one weekend and invent this workflow. Most of it appeared because something failed.
The agent changed too much, so I reduced task scope. The agent repeatedly misunderstood where logic belonged, so I improved the persistent architecture documentation. The agent invented an API behavior that looked reasonable, so I started making API contracts explicit. A cross-cutting impact only appeared after implementation, so I added preflight checks. Tests passed while the resulting behavior still didn’t answer the actual business question, so I started comparing the implementation back to the original task contract.
A semantic AI component once selected something plausible but less relevant than another candidate. The fix wasn’t to write an increasingly clever hard-coded matcher. It was to make the selection semantics explicit, preserve primary/secondary ranking, validate outputs against an application-controlled candidate set, and add regression tests.
That pattern matters more to me than any individual prompt.
Failure → identify why the agent had room to make that mistake → reduce that ambiguity next time.
It feels much more durable than collecting “10 best prompts for coding agents.”
Some things still make me slow down
There are areas where I give agents significantly less freedom: authorization, tenant isolation, concurrency, idempotency, payments, destructive migrations, data retention, security boundaries, and anything where one subtle error can become a production incident or a data leak. The agent may still write the implementation, but those areas get more explicit constraints and more review.
If code creates an order or performs a payment, “works on the happy path” isn’t a very interesting property. What happens on retry? What happens if the request arrives twice? What happens after a timeout where the caller doesn’t know whether the operation succeeded? What guarantees do we have at the database boundary? Similarly, in a multi-tenant system an elegant query isn’t elegant if it forgot the tenant predicate.
This is where AI-assisted engineering can get dangerous in a specific way. Generated code often looks reasonable. Obvious nonsense is easy to reject, but plausible code with one missing invariant is much harder to catch. The agent can generate the change, and it can’t inherit accountability for it.
Context engineering is becoming an engineering skill
There’s another shift hidden inside this workflow: a significant part of the work is now context engineering. What should always be available? What belongs in architecture documentation, and what only in a task contract? What should the agent retrieve from code rather than have copied into a giant prompt? Which rules are global, and which apply to one subsystem? Which workflows deserve automation, and which instructions are going stale?
That’s why I find repository-native instructions interesting. GitHub, Cursor, Claude Code and similar tools are all moving toward persistent or scoped instructions instead of requiring one enormous prompt at the start of every session. For someone new to coding agents, this may be one of the highest-leverage things to learn early:
Check what your tool supports for persistent project instructions.
Don’t keep repeatedly telling the agent:
We use xUnit.
Do not access Infrastructure from Domain.
Use tenant context.
Do not create migrations unless asked.
Run these tests after changing this area.
If those are stable project rules, they probably belong somewhere more persistent than today’s chat.
There’s a trap here too: more context isn’t automatically better context. A 40-page instruction file full of obsolete decisions can be worse than no instructions. The useful question isn’t
How much context can I give the model?
but
What is the smallest amount of reliable context that prevents expensive misunderstanding?
Vibe coding and agentic engineering can coexist
I don’t see these as competing religions. There are days when I absolutely want vibe coding. I want to say:
Make me a quick visualization of this.
Or:
Build a tiny tool that parses these files.
Or:
Try three UI approaches and let me click through them.
Speed is the point there, and if the experiment fails I throw it away. That’s a wonderful use of AI.
Once something becomes part of a system I expect to maintain, deploy, secure, and trust, my behavior changes. The feedback loop gets more explicit, and the specification, boundaries, tests, and review all matter more, because “seems to work” costs something different at that point.
So for me it isn’t a question of vibe coding being bad and agentic engineering being good. Vibe coding optimizes exploration, and agentic engineering optimizes controlled delivery. Sometimes I need one and sometimes the other, and the mistake is using the first operating mode while believing I’m doing the second.
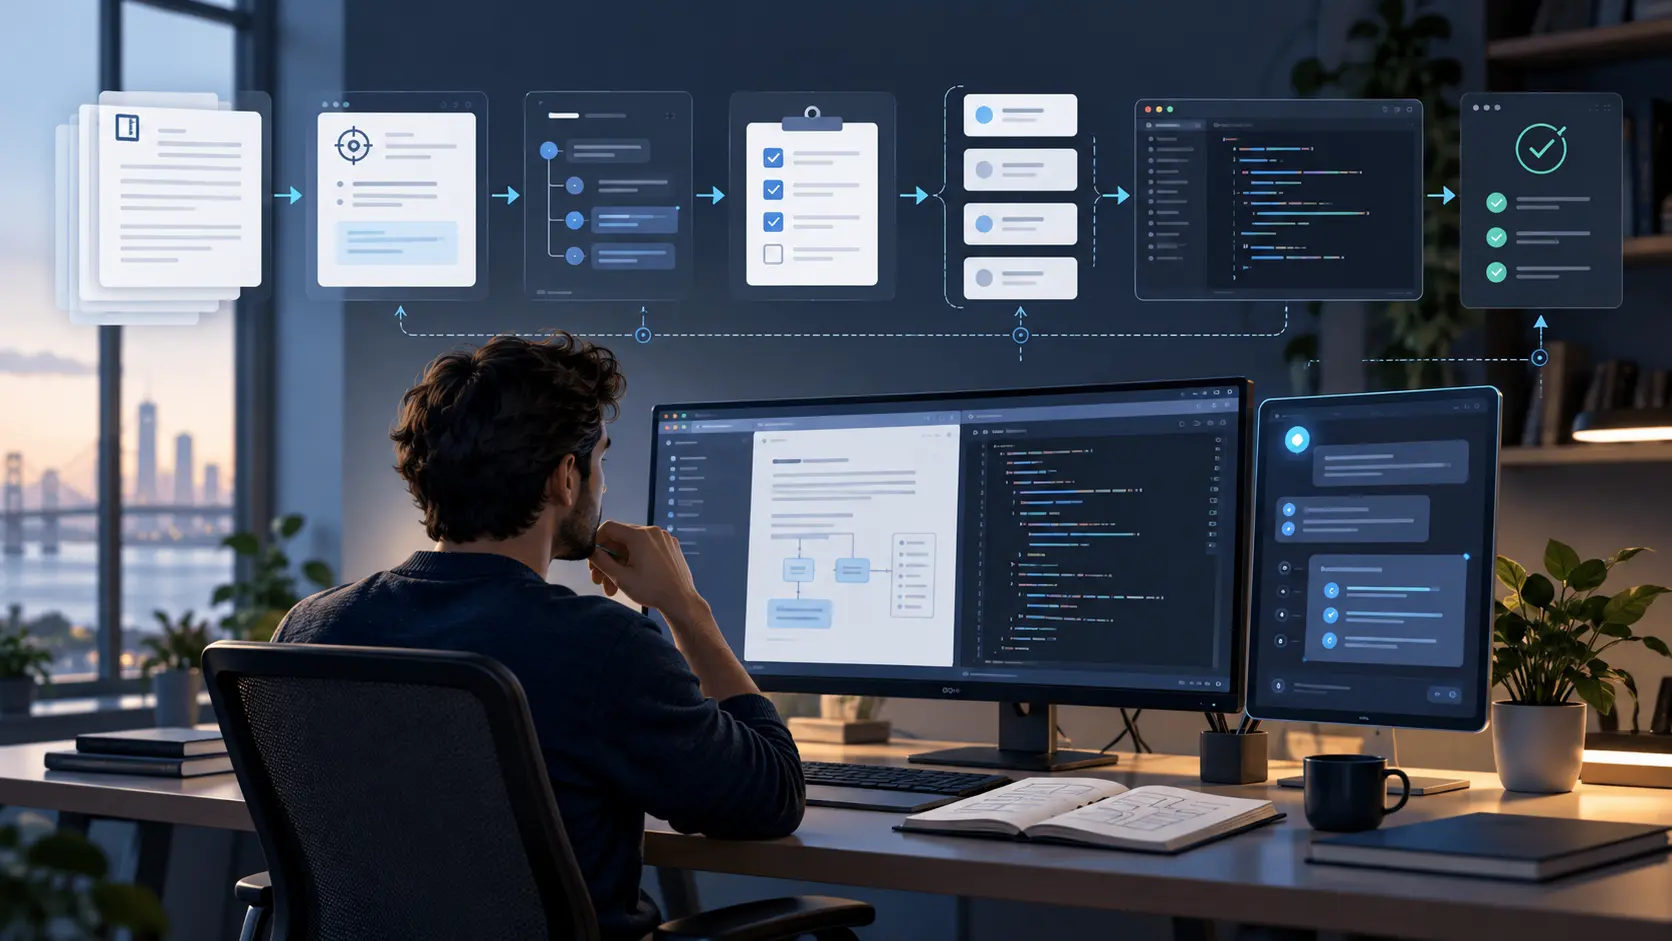
My current workflow in one picture
At the moment the process in my head looks something like this:
Persistent repository context
          ↓
      Task contract
          ↓
         Plan
          ↓
    Preflight audit
          ↓
     Bounded slices
          ↓
    Implementation
          ↓
  Build + targeted tests
          ↓
        Diff review
          ↓
Postflight against contract
Not every task uses every box. A two-line CSS fix doesn’t deserve a ceremony, and the amount of structure should scale with the risk and ambiguity of the task. That may be the most important part of the workflow:
Use process where the cost of misunderstanding justifies it.
Better agents do not make structure obsolete
Coding agents are improving quickly, and some of the guardrails I use today may become unnecessary. Models will hold more context, repository understanding and planning will improve, and agents will get better at running tests, reviewing their own changes, and coordinating specialized subagents. Modern tools already expose subagents, hooks, checkpoints, skills, sandboxing, and automated verification that make much longer autonomous workflows practical.
So I don’t expect my exact workflow to stay unchanged. But I suspect the deeper pattern will survive. As generation gets cheaper, judgment becomes more valuable. As agents become more autonomous, boundaries become more important. As more code can be produced in less time, reviewing the right things gets harder, not easier. And as models get better at producing plausible implementations, being explicit about what “correct” means matters more.
The question “Can the agent write this code?” is gradually getting less interesting, because usually the answer is yes. The more useful questions are:
- Did it understand the system?
- Did it solve the right problem?
- Did it preserve the invariants?
- Can I verify what it changed?
- Would I be comfortable owning this change in production?
My current workflow is probably not final, and I’m sure better models, along with more experience on my side, will change parts of it. But one thing has become much clearer to me:
Better agents do not make engineering structure less important. They make good structure more valuable.